My screw-up: LTX 2.5 shot with a photocopied encoder. Big labs file their failures away; I frame mine
Usually I redo other people's demos and show where they break. This time ours broke: we shot with a copy of the 13/08 encoder instead of the official one from 17/08, and our launch log proudly showed us the fingerprint… of an empty file. On our White Rose and Kira scene, 3 take pairs out of 6 are twins, 3 become a different take, and when one is better, it's the official. Big labs file this kind of screw-up away. I frame it, takes, measurements, and bill included.
In-house analysis. Official repo files checked on 02/11/2026; video bench rerun on 02/11/2026; scene shot on 26/10/2026.
 MilkyThe one who tests
Checked by a 2nd AI
In short
- The text encoder reads your prompt before the model draws. Ours had 2,412 more bytes than the official one and a different fingerprint.
- Same time and cost: $0.23 for 6 takes in each version. Shoot 100 like these: about $3.8 on both sides (our math).
- Verdict on six pairs: the old copy is not equivalent and tends to make the image less stable, without losing on every roll.
What happened
Our LTX 2.5 files came from an unofficial copy of the Lightricks repo, whose text encoder was not the publisher's (Hugging Face public API):
| Our copy | Official (Lightricks) | |
|---|---|---|
| Upload date | 13/08/2026 | 17/08/2026 |
| Upload message | "mirror … from Lightricks/LTX-2.5" | "Update Gemma 4 12B text encoders: " |
| Size | 15,372,971,786 bytes | 15,372,969,374 bytes |
| sha256 fingerprint | 09a89e084de1… | 6ce688a0aa98… |
The copy dates from four days before Lightricks' update: our read is that we were shooting with the old version. The model's other four files are identical to the official ones (fingerprints).
What it changes
Two tests, two sets of settings, never mixed.
1. The studio's White Rose + Kira scene
Same scene shot twice, same seeds (42 and 7), only the encoder changes. Settings, which are not our bench's: LTX 2.5 dev bf16, distilled LoRA 0.5, character LoRA 1.0, 1920 × 1088, 3 shots × 2 seeds = 6 pairs.
MAD is the average gap between pixels (0 to 255), SSIM structural similarity (1 = identical). These are difference measures, not quality. For scale: the gap between two different seeds with the same encoder, the size of a real "different take."
| Pair | MAD | SSIM | Verdict |
|---|---|---|---|
| Shot 02, seed 42 | 2.0 | 0.955 | Nearly identical |
| Shot 02, seed 7 | 2.8 | 0.920 | Nearly identical |
| Shot 03, seed 7 | 2.1 | 0.955 | Nearly identical |
| Shot 01, seed 42 | 15.9 | 0.784 | Different take, draw |
| Shot 01, seed 7 | 19.3 | 0.758 | Different take, official better |
| Shot 03, seed 42 | 33.4 | 0.638 | Different take, official clearly better |
Between two seeds, MAD is 19.0 (shot 01), 11.7 (shot 02), and 15.0 (shot 03): the first 3 pairs are 4 to 7 times under that gap, the other 3 reach it or pass it. In these 3 takes, the old version moves 1.3 to 4 times more, despite "Static camera".
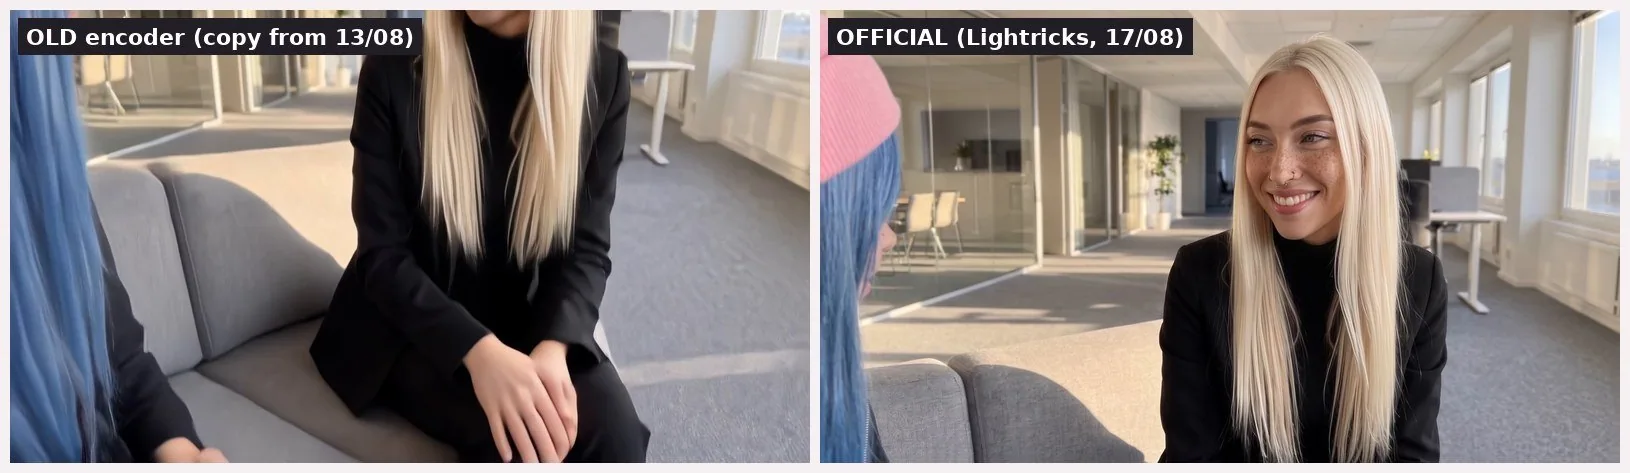
Shot 03, seed 42: the big gap. With the old copy, the camera tilts down starting at 2.2 s and loses Kira's face during her line (lip-sync: correlation of −0.07, versus 0.48). With the official one, the frame stays fixed.
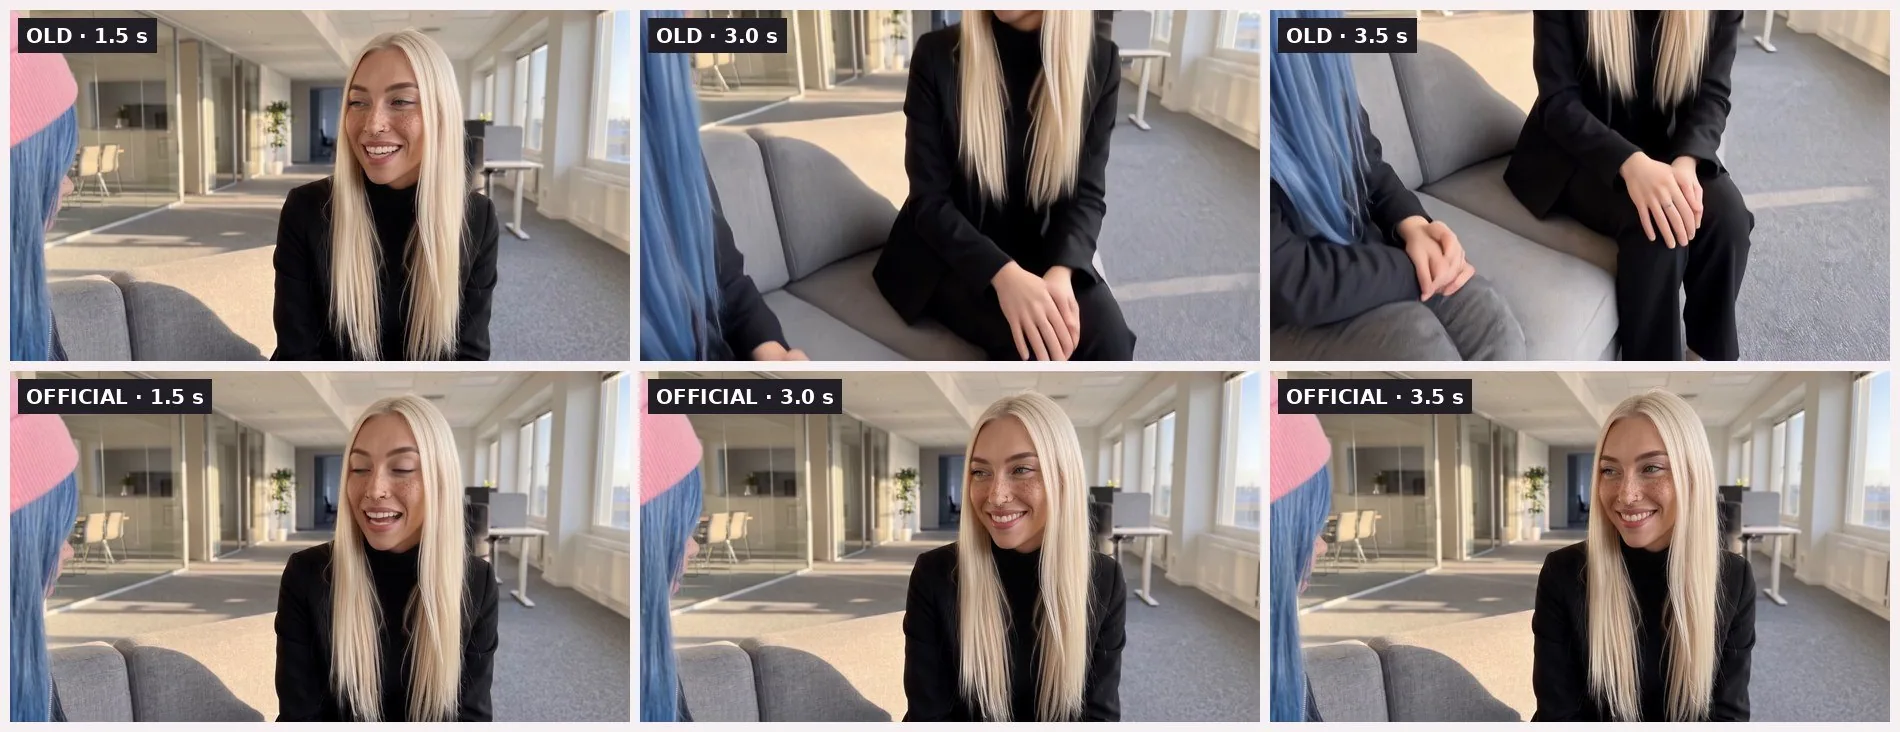
Shot 01, seed 7: the set that moves. With the old copy, the couch changes shape between 1.1 and 2.3 s, then everything snaps back at once. With the official one, the set stays stable.
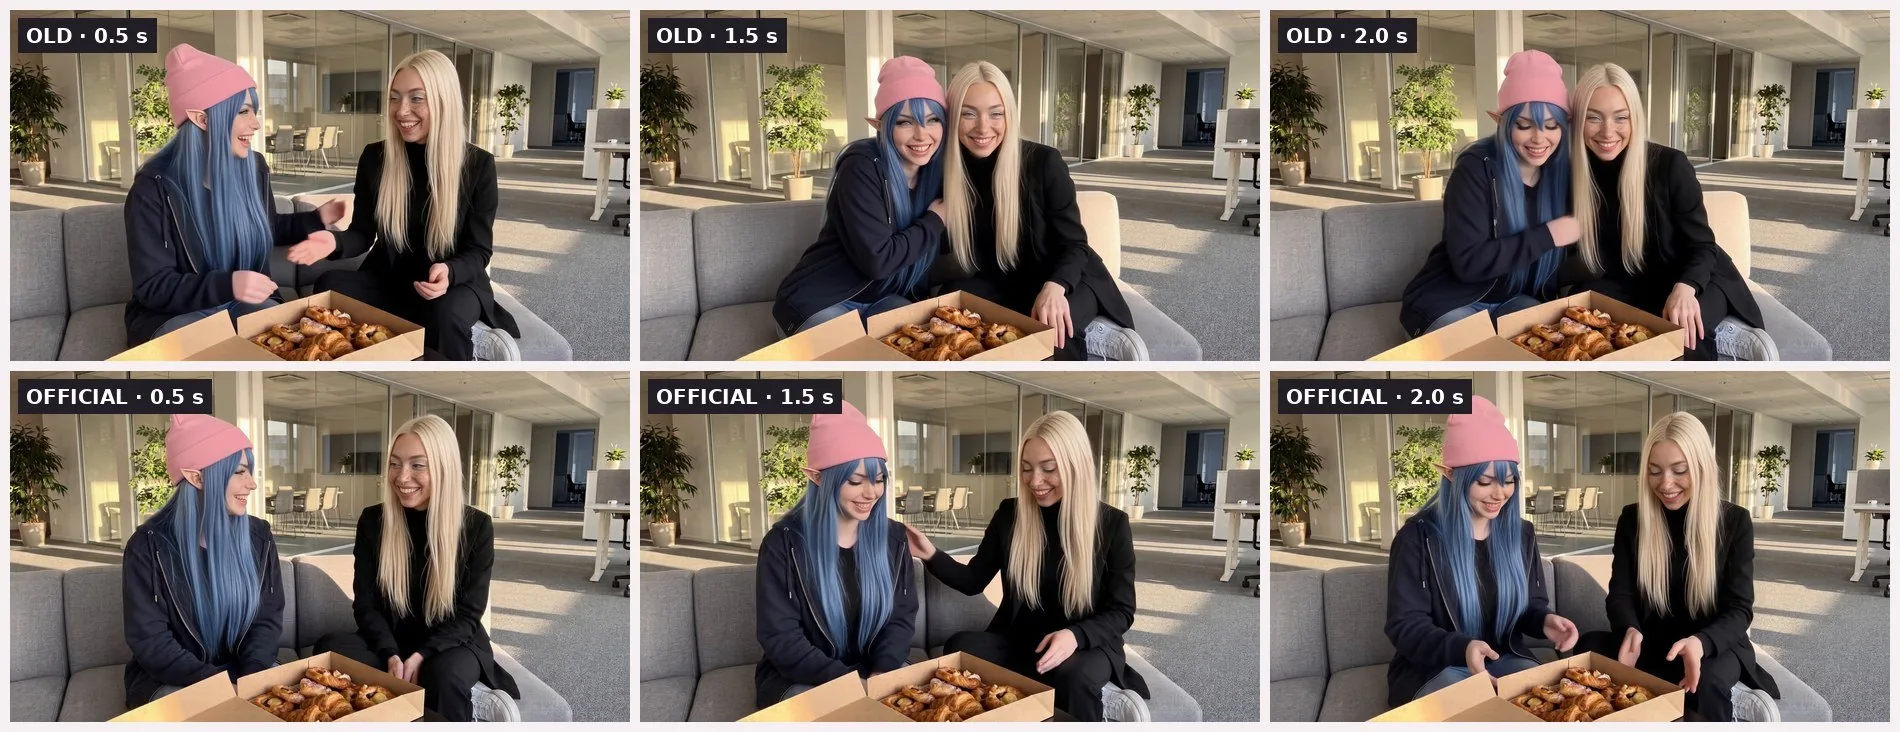
Shot 01, seed 42: a draw. The official one performs the box pass better but duplicates it; the old one is cleaner, the action less crisp.
Bottom line: the old copy is not equivalent to the official one and tends to make the image less stable, without losing on every roll. Base: six pairs, two seeds.
2. Our V0 video bench, rerun with the official encoder
Four 5 s shots (sidewalk, café, map, night), one roll each, seed 2210, LTX 2.5 distilled at 704 × 1280. The "old" one dates from 26/10; on 02/11, I reran it with the official encoder, same images, prompts, and settings, same GPU model.
| Shot | SSIM | PSNR | Old: time, cost | Official: time, cost |
|---|---|---|---|---|
| Sidewalk | 0.90 | 24.2 dB | 44.3 s, $0.0306 | 44.7 s, $0.0309 |
| Café | 0.91 | 25.0 dB | 27.7 s, $0.0192 | 27.0 s, $0.0187 |
| Map | 0.78 | 22.4 dB | 27.8 s, $0.0192 | 27.7 s, $0.0192 |
| Night | 0.92 | 27.6 dB | 27.3 s, $0.0189 | 27.4 s, $0.0190 |
PSNR (in dB) is another measure of the gap: the lower it is, the more the videos differ. They say there's a difference, not which is better, so I looked. The first shot loads the model, which is why its time is longer.
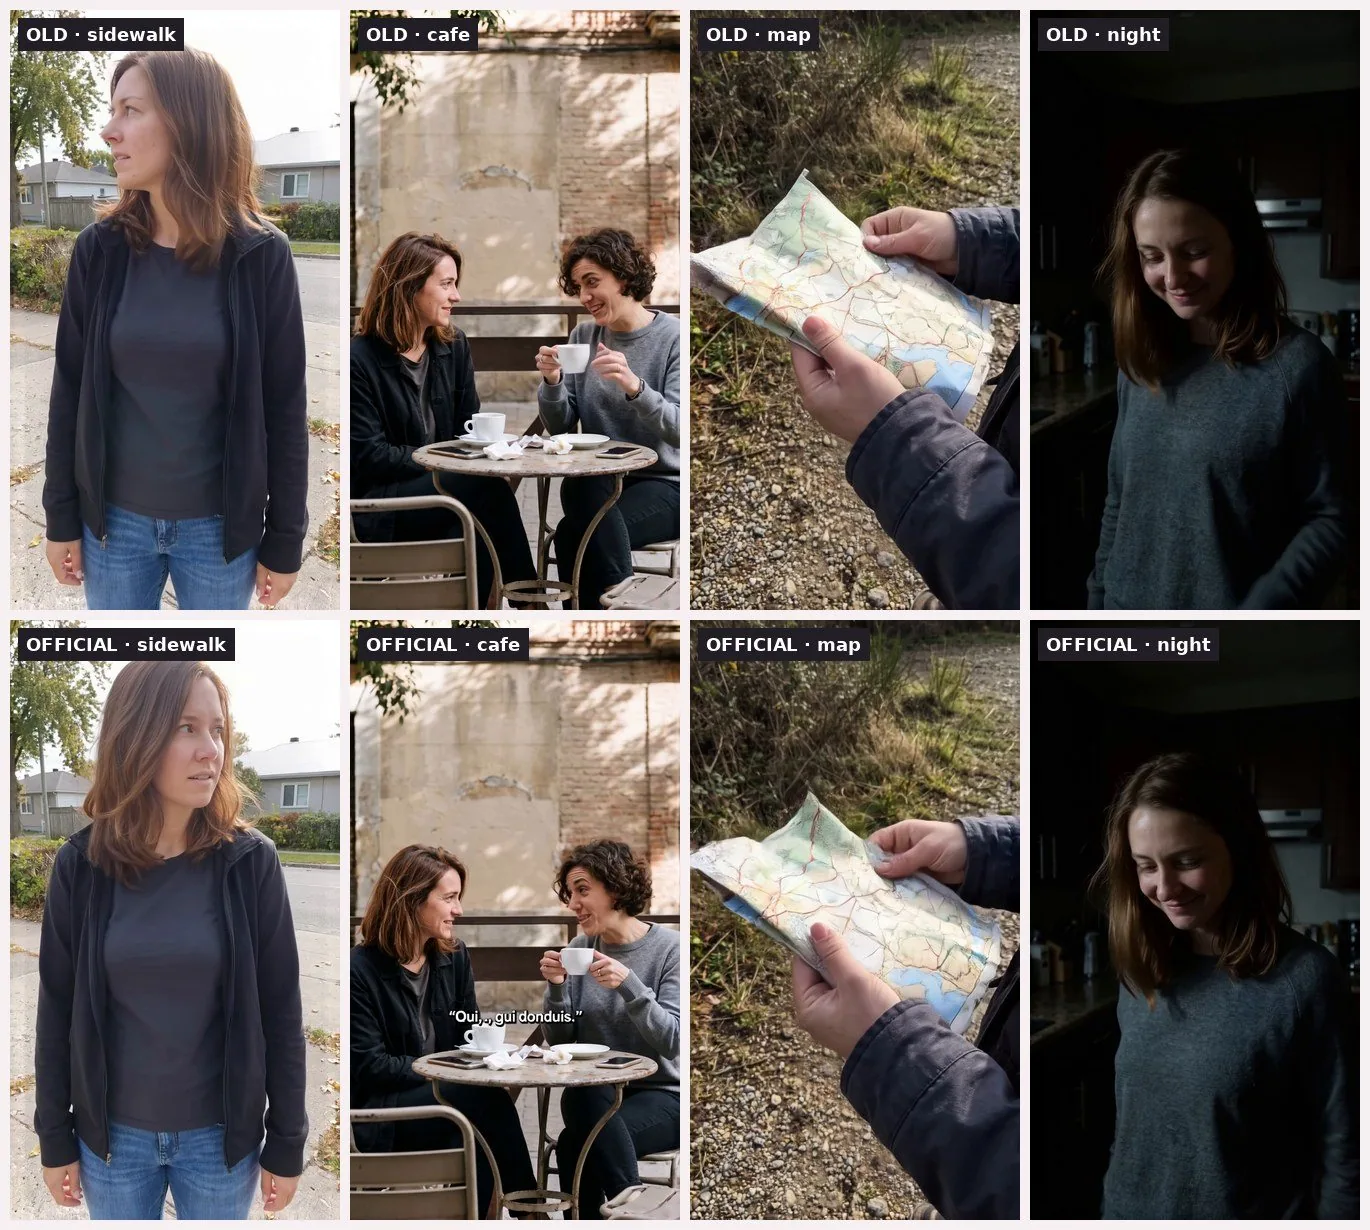
On a single roll per shot:
- Sidewalk. The prompt says she looks to her left. Both versions take another path (around 3.5 s, the old one is in profile, the official one almost face-on), but both end with her head turned to her right, her face hidden by her hair: neither follows the prompt.
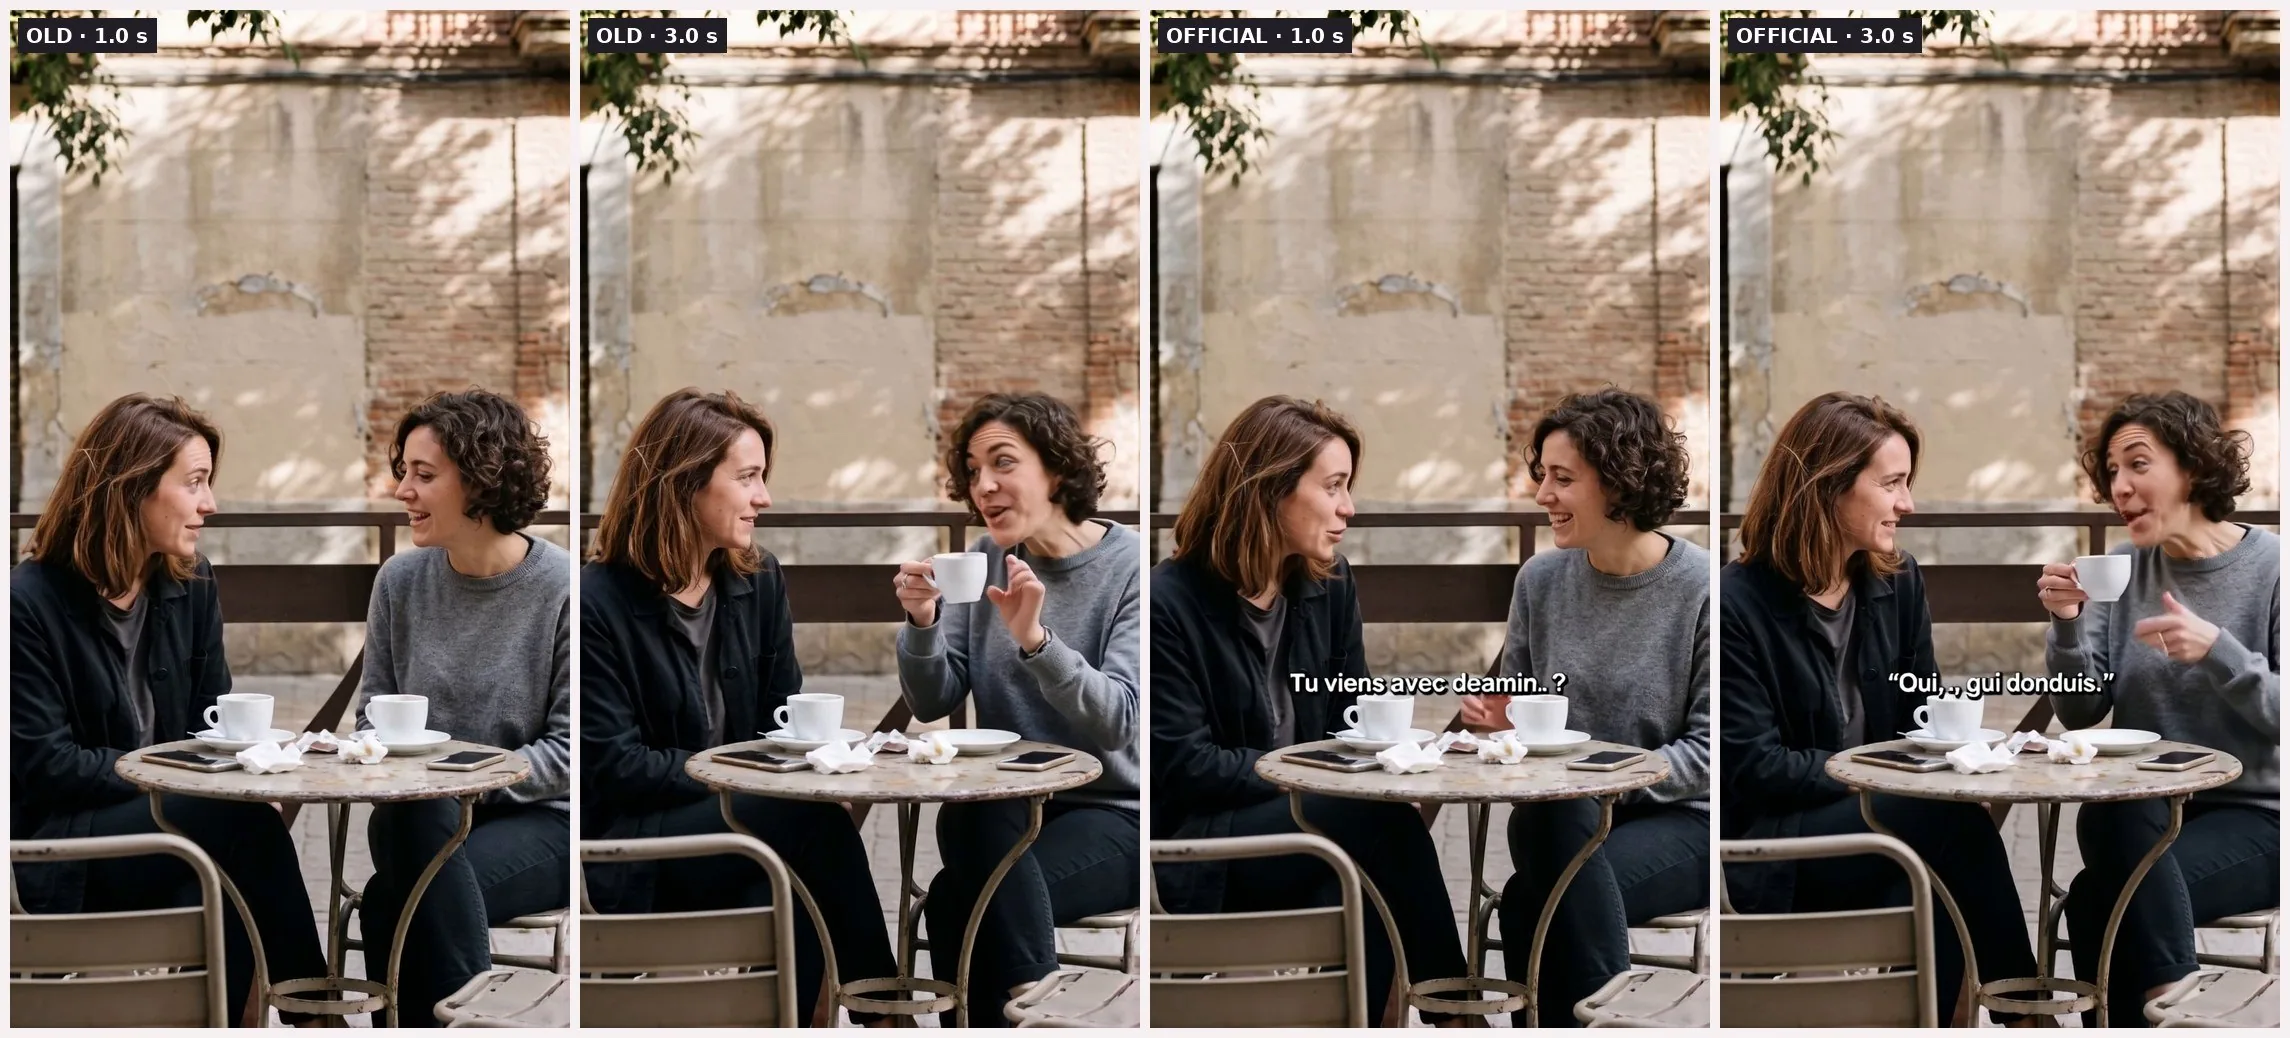
- Café. With the official one, faulty subtitles burn in ("deamin", "gui donduis") despite "no subtitles"; none with the old one. A single roll: we'll see if it strikes again.
- Map and night. No winner.
3. Time and cost
Bench: 127.1 s and $0.0879 for the 4 shots with the old copy, 126.8 s and $0.0878 with the official one. If you make 100 shots of 5 s: $1.92 versus $1.90, a two-cent gap (our math: duration × $2.49 an hour). Scene: 221 s versus 224 s, $0.23 each for 6 takes (prorated from compute time); if you make 100: about $3.8 on both sides. A difference of seconds is noise.
Rerunning the bench cost us 6 min 28 s of pod time, or $0.27 at the hourly rate.
How we caught it
- Sizes and fingerprints. A sha256 fingerprint is a file's mathematical serial number. Compared with the official repo, four of our five files matched, the encoder did not.
- The trap. The shoot's launch log showed, for the encoders, a fingerprint starting with
e3b0c44298fc. That is the fingerprint of an empty file: the command that was supposed to read the file had failed at launch, and the fingerprint was computed on nothing. I recomputed the fingerprint of an empty input myself on 02/11: same start.
Lesson: check the fingerprint AND the command that computes it, or you end up checking nothing with great confidence. The only ones that count are those measured on the machine and compliant with the API.
What we fixed
- We shoot with the official encoder, taken from the Lightricks repo. The five files are checked by size and fingerprint before any generation: a missing or non-compliant file blocks everything.
- The V0 bench is rerun: the numbers above. The scene itself was not reshot: we measured the 12 existing takes.
What we don't know yet
- What changed in the encoder. The title of Lightricks' upload, "Update Gemma 4 12B text encoders:", announces an update without detailing it, and the pages I read say nothing more.
- Whether the gap shows up elsewhere: six pairs, four shots, one roll each, is too little for a rule. Same for the café subtitles.
Key terms
- Text encoder: the part of the model that turns your prompt into numbers.
- sha256 fingerprint: a serial number computed on a file's contents; one byte of difference, and it changes.
- MAD, SSIM, PSNR: measures of the gap between two images, not of quality.
Source passages
Show the 9 sources
| Ref. | Quote (original language) | URL |
|---|---|---|
| S1↑1↑2 | Official Lightricks/LTX-2.5 repository, int8 text encoder: 15,372,969,374 bytes; last upload 2026-08-17T13:46:36Z, « Update Gemma 4 12B text encoders: »; hash 6ce688a0aa98a5fa36a9f1e6c3f42152a498cc2b53ee8c15674c64244f91487f (read with the lab account; masked without an account) | https://huggingface.co/api/models/Lightricks/LTX-2.5/tree/main/text_encoders?expand=true |
| S2↑1↑2 | Copie comfyicu/LTX-2.5, même encodeur : 15 372 971 786 octets ; empreinte 09a89e084de1a149c3de60cfe9dfd3e5161967eb09eea39e806fcdeffdd568de ; envoi 2026-08-13T06:40:22Z, « mirror text_encoders/… from Lightricks/LTX-2.5 » | https://huggingface.co/api/models/comfyicu/LTX-2.5/tree/main/text_encoders?expand=true |
| R1↑1↑2↑3↑4↑5 | Studio scene protocol (26/10/2026): LTX 2.5 dev bf16, distilled LoRA 0.5, character LoRA 1.0, 1920 × 1088, 24 fps, euler_ancestral 2 passes, CFG 1, seeds 42 and 7; « Une seule chose change : le fichier de l'encodeur de texte » | — (in-house test) |
| R2↑1↑2↑3↑4↑5↑6 | Scene measurements: pairwise MAD and SSIM, seed reference, motion, lip sync (shot 03 seed 42: −0.07 versus 0.48); verdict: « L'ancien fichier n'est pas équivalent » and « tendance à rendre l'image plus instable », « il ne prouve pas qu'il soit pire à chaque tirage » | — (in-house test) |
| R3↑1↑2 | Scene time and cost: 221 s versus 224 s, $0.23 each, for 6 takes; pod at $2.49/h, 40 min for 50 shots, $1.66 | — (in-house test) |
| R4↑1↑2↑3↑4↑5↑6 | V0 bench rerun on 02/11/2026: same images, instructions and settings, official encoder; size and hash of the 5 files verified (« sha256 identiques : 5/5 »); pod deleted after 6 min 28 s, $0.27 at the hourly rate | — (in-house test) |
| R5↑1↑2 | SSIM and PSNR per shot (0.8977 / 24.16 dB; 0.9059 / 24.97; 0.7798 / 22.45; 0.9205 / 27.61); time and cost of each shot, taken from the .json files | — (in-house test) |
| R6↑1↑2↑3↑4↑5↑6 | Frame-by-frame review: contact sheets of the scene (shots 01 and 03) and of the bench (five moments per shot; nine moments reviewed separately for the coffee shot); burned-in subtitles with the official encoder on the coffee shot, absent from the old one | — (in-house test) |
| R7↑1↑2 | « Les lignes "encodeur e3b0c44298fc" sont l'empreinte d'un fichier vide : la commande stat a échoué au lancement »; sha256 of an empty input recomputed on 02/11/2026: e3b0c44298fc1c149afbf4c8996fb92427ae41e4649b934ca495991b7852b855; reference hashes recorded on the machine | — (in-house test) |
I don't believe a demo. I redo the test myself and show you the result, even when it's ugly. And don't make me angry, you won't like what comes next.